Meta's Prometheus Using Object Storage for Massive AI Training Jobs
The redesign cut average job ingestion time from 150 minutes to 10 minutes and reduced the longest runs to just over 3 hours, Meta said.
7 Articles
7 Articles

Meta’s Prometheus supercluster is heading for 1 million Nvidia GPUs
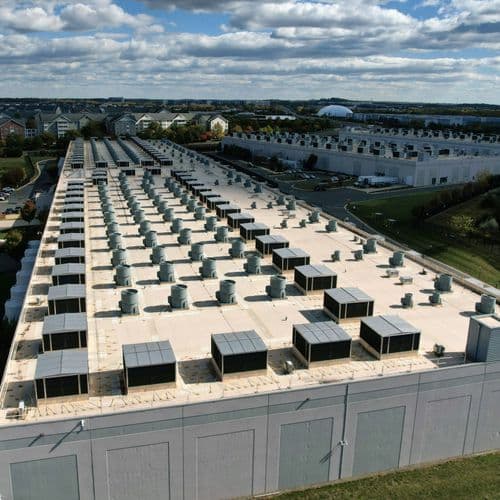
Meta’s Prometheus supercluster in New Albany, Ohio, already runs hundreds of thousands of Nvidia GPUs across several buildings, and Meta plans to grow it to about 1 million. The company set out the details in an engineering blog post on Monday. The first phase of the gigawatt-scale cluster is finished. Meta used it to train […] This story continues at The Next Web


Meta completed the first phase of Prometheus, an AI supercluster that already trained its Muse models and that the company plans to expand up to about a million GPUs. The company also detailed the NVIDIA platforms, the network, the reliability mechanisms and the energy infrastructure that sustain that expansion.


Meta Prometheus: Inside the Gigawatt Supercluster Scaling to 1 Million GPUs on GB200 and GB300 NVL72
Meta published a detailed look inside Prometheus today, the gigawatt-scale AI supercluster it is building in New Albany, Ohio. The first phase is complete and has trained the Muse family of foundation models, including the Muse Wonder models, and Meta says the site is being scaled toward roughly 1 million GPUs. Two years ago, the same campus was a conventional data center serving web traffic. The post, from Meta engineers Kevin Lee, Yashar Bayan…
Coverage Details
Bias Distribution
- 50% of the sources lean Left, 50% of the sources are Center


Factuality
To view factuality data please Upgrade to Premium